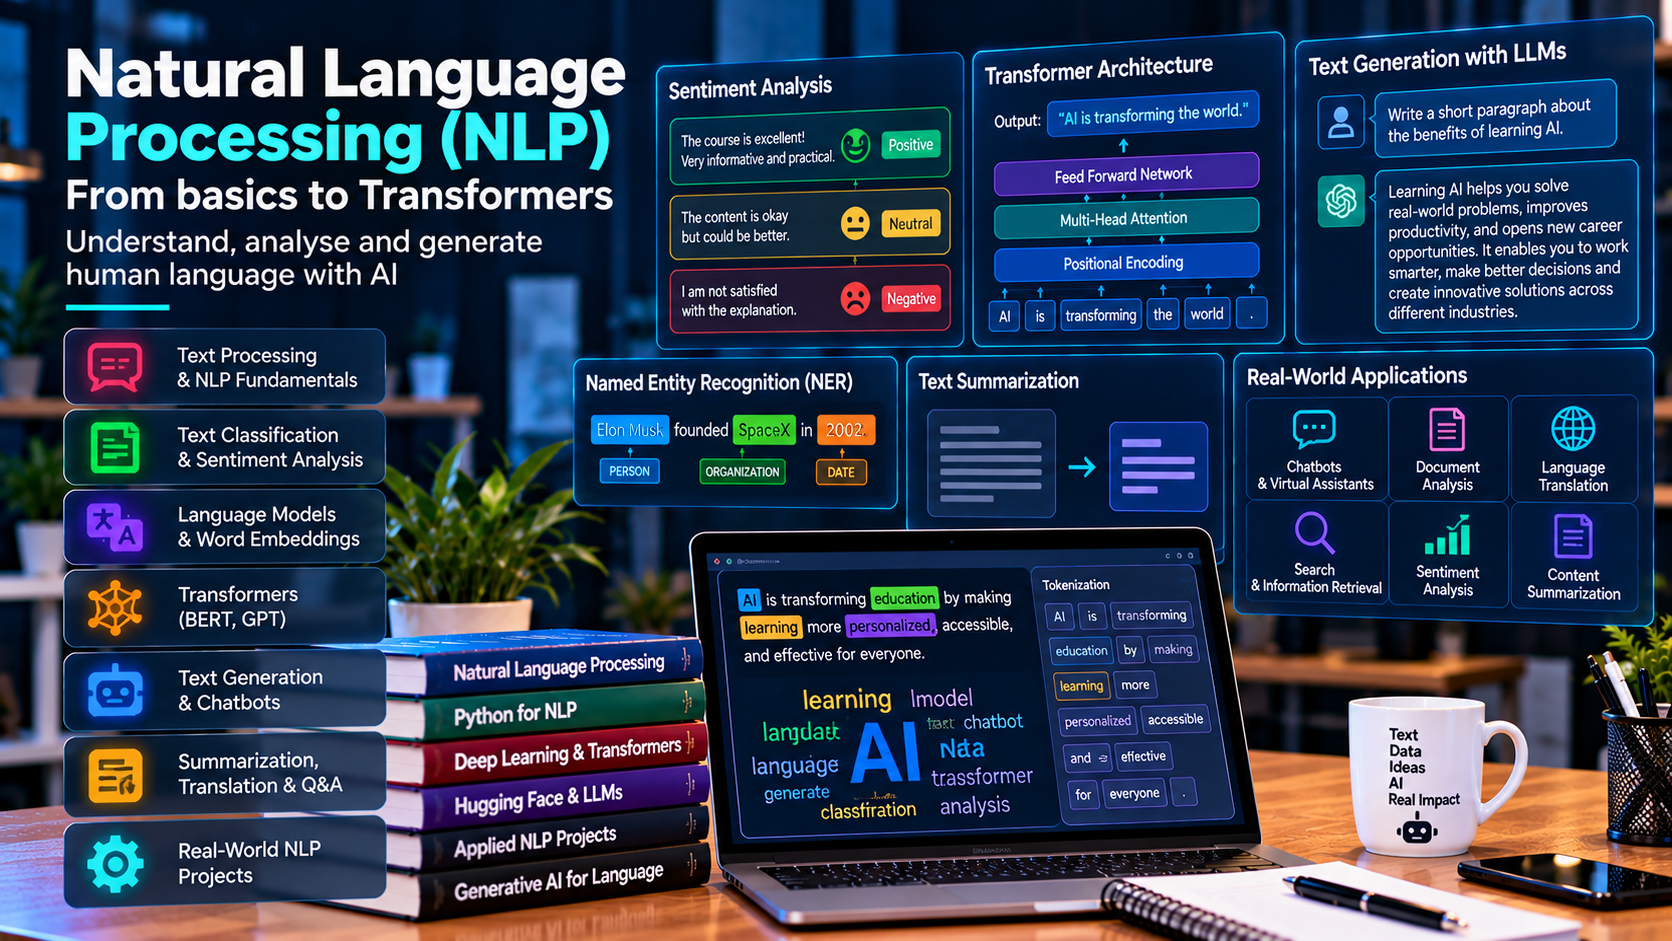
Move from traditional text processing to embeddings and transformer models, then fine-tune a classifier for practical language data. 1. Who can join Suitable for: Python developers, ML learners and data scientists Mandatory prerequisites: Python, Pandas and foundational ML concepts 2. Duration 48 live hours • Approximately 8 weeks at 6 hours per week; actual timetable to be confirmed. 3. Mode Classroom - Thaiyur / Kelambakkam, OMR Chennai (subject to schedule) Live Online (subject to schedule) 4. Syllabus — five modules
Module 1: Classical Text Processing: Tokenization, Stemming, TF-IDF & N-Grams Learning outcome: Create tokenization and TF-IDF pipelines. Module 2: Word Embeddings & Vector Space Modeling (Word2Vec, FastText) Learning outcome: Use dense word embeddings to represent text. Module 3: Sequence Modeling for Sentiment Analysis & Topic Classification Learning outcome: Train a baseline text classification model. Module 4: Transformer Architecture: Self-Attention Mechanisms, Encoder-Decoder Models Learning outcome: Explain transformer attention at a conceptual and practical level. Module 5: Practical Fine-Tuning with Hugging Face Ecosystem for Enterprise NLP Learning outcome: Fine-tune and evaluate a pretrained text classifier. 5. Practical project Source capstone title: Build a Multi-Class Customer Feedback Classifier using BERT Student deliverable: A multi-class customer-feedback classifier with preprocessing pipeline, trained transformer model and a performance report.
6. What is included Live trainer-led sessions Practical assignments Sample code or templates, as applicable Project feedback Learning assessment Perizona course-completion certificate subject to assessment 7. Upcoming batch
Start date: To be announced. Students can register interest; dates are shared only after confirmation.